
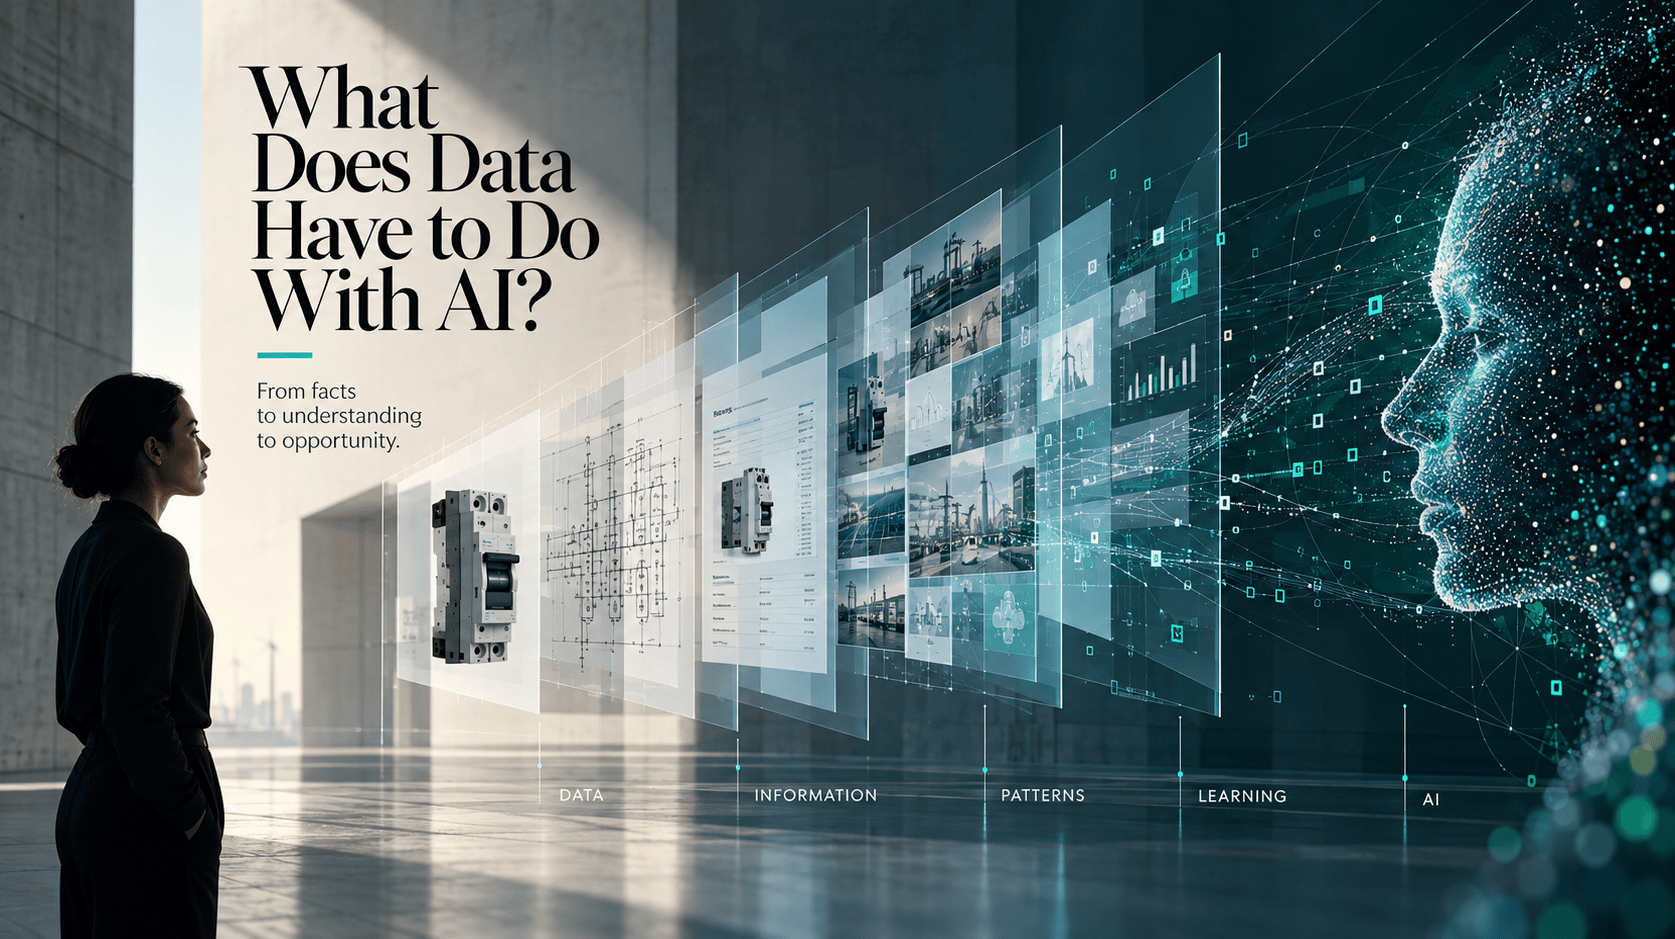
At its core, AI is code that reads data. It then algorithmically identifies patterns, correlations, and reports the results delivering it as information. As the saying goes, “garbage in, garbage out.” If it reads, or interprets, data incorrectly, erroneous information is provided. Provide good, quality data and the quality of the output increases.
Data can take the form of product data, information from your ERP, CRM, and qualitative data such as staff observations that is digitized to support knowledge transference.
At the recent eBiz conference, Lucy Edosomwan, who is responsible for Data Governance & Digital Integrity, and I had a discussion about the relationship of data and AI. Lucy also participated on a panel discussion how data will be converted to information to impact customers, rather than primarily being used for supply chain and eCommerce.
She shared her thoughts on the importance of data to an AI initiative.
What Does Data Have to Do with AI?
Artificial intelligence is quickly changing how businesses search, automate, analyze, and use information. Across industries, organizations are exploring what AI can do, where it can create value, and how quickly they can put it to work.
I see this conversation firsthand in my work with product data at Siemens, where the quality and structure of information directly affect how it can be used across people, systems, and technology.
Recently, I had the opportunity to speak on a panel about people, data, and AI in the electrical industry. And while there is a lot of excitement around what AI can do, I believe understanding its potential starts with something much more fundamental: Data.
Data is a collection of facts, observations, measurements, or knowledge.
On its own, data may or may not tell you very much. It becomes more useful when we give it structure and context. That is how data becomes information—something we can understand and, more importantly, use.
Think about the number 20.
Twenty products? Twenty dollars? Twenty volts? Twenty amps?
The data exists. But without context, its usefulness is limited. Once we understand what the number represents and what it relates to, data becomes information we can understand and use.
And once information is clear, accurate, and consistent, something else becomes possible:
We can recognize patterns.
Patterns allow us to learn. From there, we can analyze information, identify relationships, perform mathematical computations, forecast outcomes, and make predictions.
Humans have always done this.
AI changes the scale.
Artificial intelligence allows us to process and use amounts of data that extend beyond human capacity. Machine learning, a type of artificial intelligence, can use large amounts of data to identify patterns and learn relationships.
Those relationships can then be used to classify information, make predictions, generate content, or support decisions. This means that when we talk about the potential of AI, we are also talking about the quality of the data behind it.
An AI system may be able to process millions of pieces of information much faster than a person can. But speed and scale do not automatically make the underlying information accurate.
AI can expand what we can do with data. It cannot make poor data good.
That distinction becomes increasingly important as our information moves across more places.
Think about a single electrical product.
Its information may exist on a manufacturer’s website, a distributor’s website, within technical documentation, across internal systems, in search results, and eventually within an AI application.
If the product is named one way in one system, categorized differently in another, and represented with an outdated specification somewhere else—which version should the machine trust?
That is not necessarily an AI problem.
It is a data problem.
Quality data is accurate, complete, consistent, assessed, verified, managed, and governed. As that information moves between systems and users, its integrity should move with it.
Get that foundation right, and the possibilities begin to expand.
We can improve search and findability. We can sort, filter, compare, and calculate. We can move trusted information between internal teams, manufacturers, distributors, partners, and customers.
Then AI gives us another layer of possibility.
An AI system may be able to process millions of pieces of information much faster than a person can. But speed and scale do not automatically make the underlying information accurate.
Information can be summarized, classified, personalized, recommended, translated, or transformed into different formats. Technical documents can become structured information. Product attributes can support recommendations. Large collections of information can become easier to search, understand, and use.
Information that once required someone to manually search through hundreds of documents can potentially be retrieved in seconds.
This all becomes possible when we start by making the information understandable.
So, how do we structure data?
If structure is what turns raw data into usable information, then preparing for AI begins well before choosing a model or tool.
It begins with understanding what you have.
- Start by inventorying your data. Identify where it lives, what formats it takes, who creates it, and where it is used. You cannot effectively structure information you cannot see.
- From there, define what the data means. Establish common definitions for the terms, fields, attributes, and categories being used. If “product type” means something different across three systems, simply connecting those systems will not solve the problem.
- Next, organize the relationships. Determine how information should be grouped, classified, and connected. This is where taxonomies, hierarchies, metadata, and relationships begin to give individual pieces of data greater context.
- Then, establish standards. Decide how information should be named, formatted, measured, and maintained. Naming conventions, required attributes, units of measurement, and formatting rules help make information consistent enough to compare and use.
- Finally, govern the structure. Define ownership, validation rules, sources of truth, and processes for maintaining the data over time.
The goal is not simply clean data.
It is data that is defined, organized, consistent, connected, and governed enough to retain its meaning wherever it is used.
And that brings us back to AI.
The more context a machine has around our information—what something is, what it means, how it relates to something else, and whether it can be trusted—the more useful that information becomes.
So perhaps the question before “What can we do with AI?” is much simpler:
What should we do with our data?
About the Author: Lucy Edosomwan works in product data and data governance at Siemens Electrical Products, where she focuses on the structure, governance, and integrity of complex product information. Her work explores how trusted data can support digital commerce, automation, analytics, and artificial intelligence across industrial organizations.
Lucy writes and speaks about data strategy, AI readiness, and the relationship between people, information, and emerging technology.

Trending Now

ABB welcomes ElectroRep; Panasonic Joins ESA

What Does Data Have to Do With AI?
You may also like


